Infinite-Sum Modeling
In one line
Policy scenarios and trade shocks should not be stuck on local toolchains, hand-built folders, and hard-to-reproduce scripts.
EconMOD turns region/sector aggregation, closure and shock setup, and general-equilibrium solves into an auditable, collaborative server workflow.
Why it exists
For applied CGE / GTAP work, the real bottleneck is rarely “writing the equations.” It is usually:
- Dimension control: every step from a global base database to an interpretable region×sector mapping must be checkable;
- Scenario engineering: closures (Book / Short / Long / Self) and shock variables must align before submit—not after a failed solve;
- Compute and collaboration: heavy jobs should queue on the server, with structured results—not intermediate files scattered on personal disks;
- Numerical trust: critical gates (aggregation accuracy, reference-scenario welfare EV, and so on) must be re-verifiable by the team.
EconMOD is built for that chain—not another dashboard, but a runnable modeling workbench.
Core analysis path
From an authorized base database to searchable results, the product path is clear:
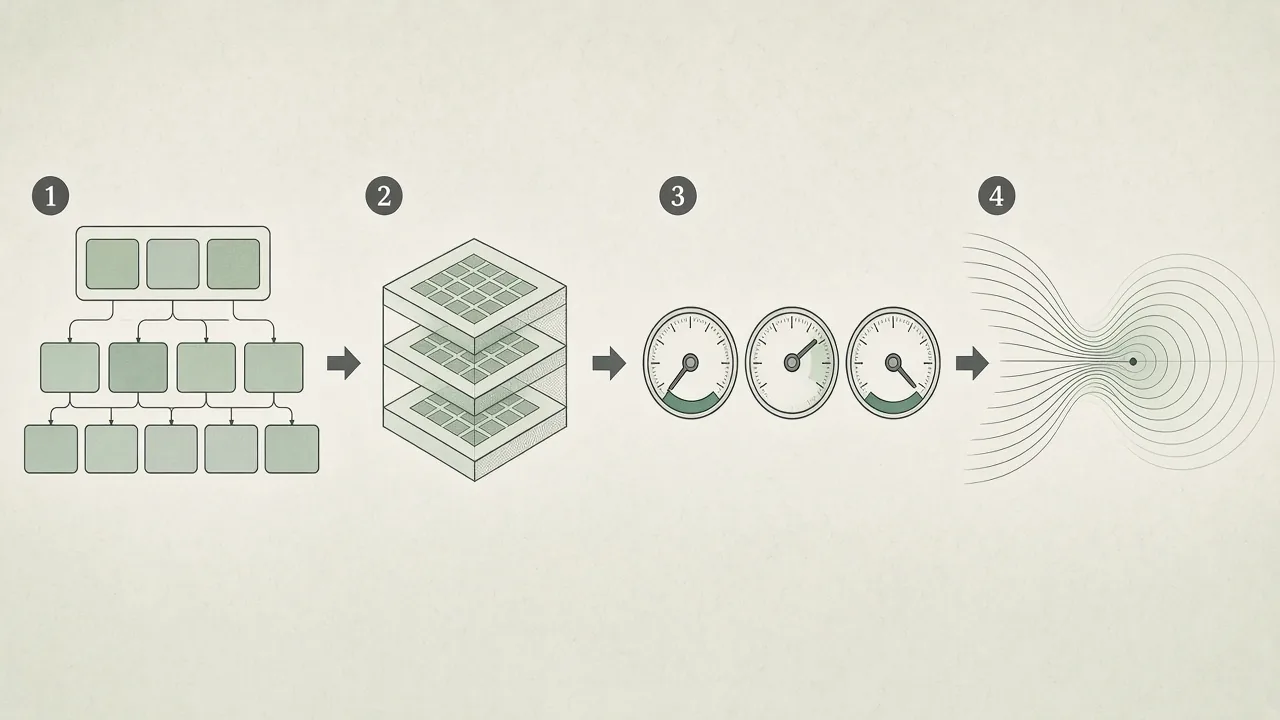
Aggregation mapping → run aggregated database → pick a database and build a simulation → solve
| Stage | What you do | What the system delivers |
|---|---|---|
| Aggregation | Define region / sector groups and mappings (including standard templates) | A derived aggregated database in your workspace |
| Simulation | Choose closure presets, solution method and steps; edit shocks structurally | A submittable scenario (with exogenous / shock consistency checks) |
| Solve & results | Queue runs on the server; browse EV, macros, and variable slices | Job logs + full solution results, exportable for comparison |
Base databases are published and authorized by administrators; personal derived databases belong only to you—so consulting projects and research groups can run in parallel without contaminating each other.
Main modules (live UI)
Screenshots below are from a running EconMOD workbench.
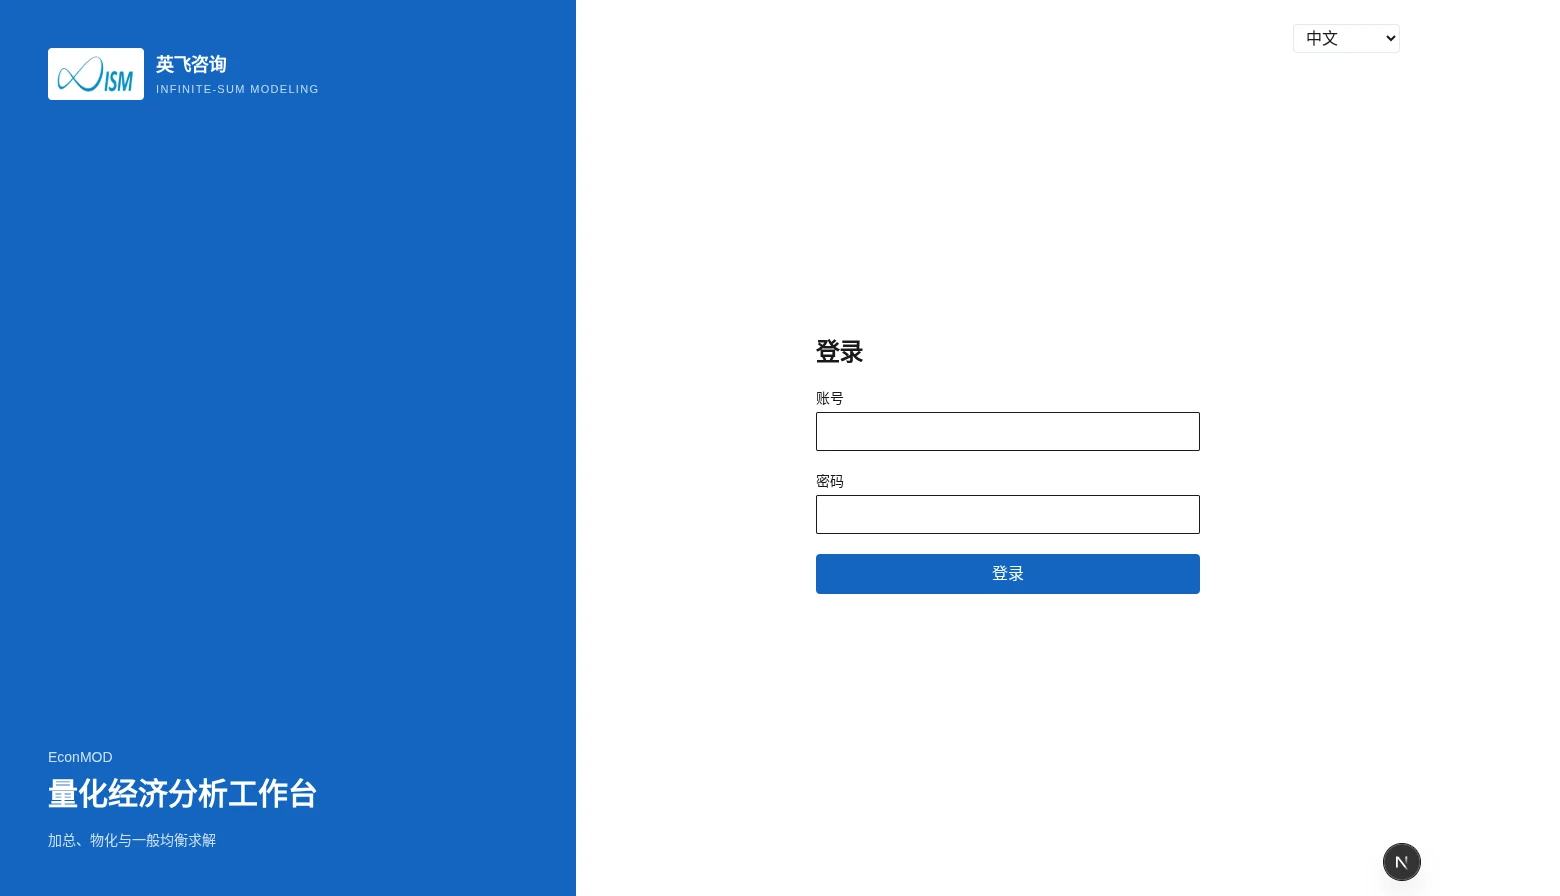
Sign-in
Use an assigned account to enter your workspace; the UI supports Chinese and English.
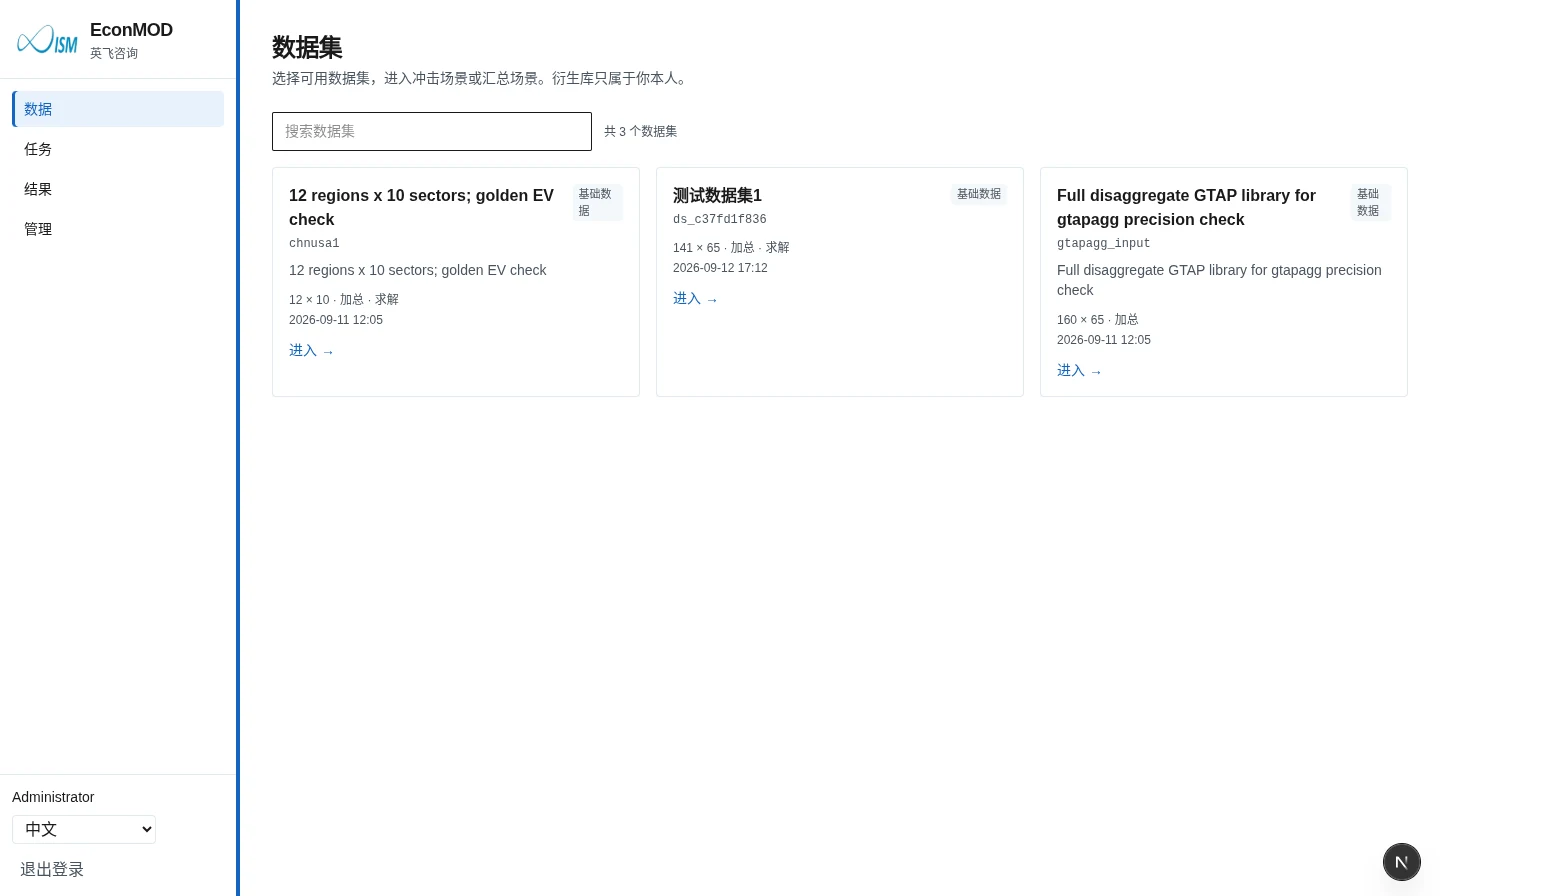
Data: authorized bases and scenario entry
In Data, browse authorized base databases, filter by region×sector size, and open shock or aggregation scenarios. Derived databases belong only to you.
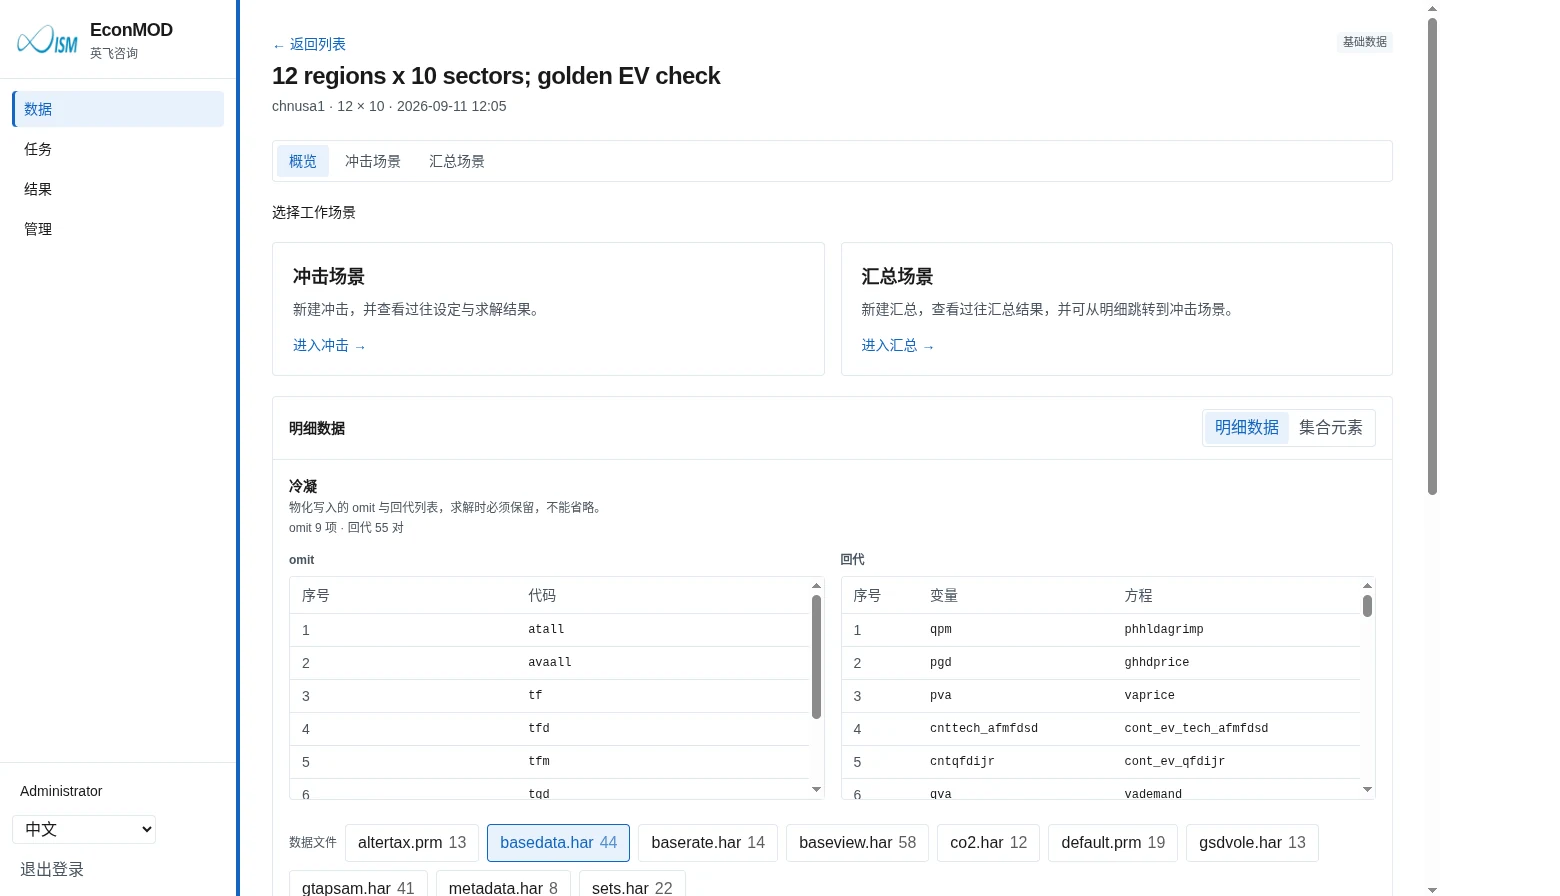
On a base overview, two paths are explicit—Shock scenarios and Aggregation scenarios—with detail tables and condensation settings you can verify.
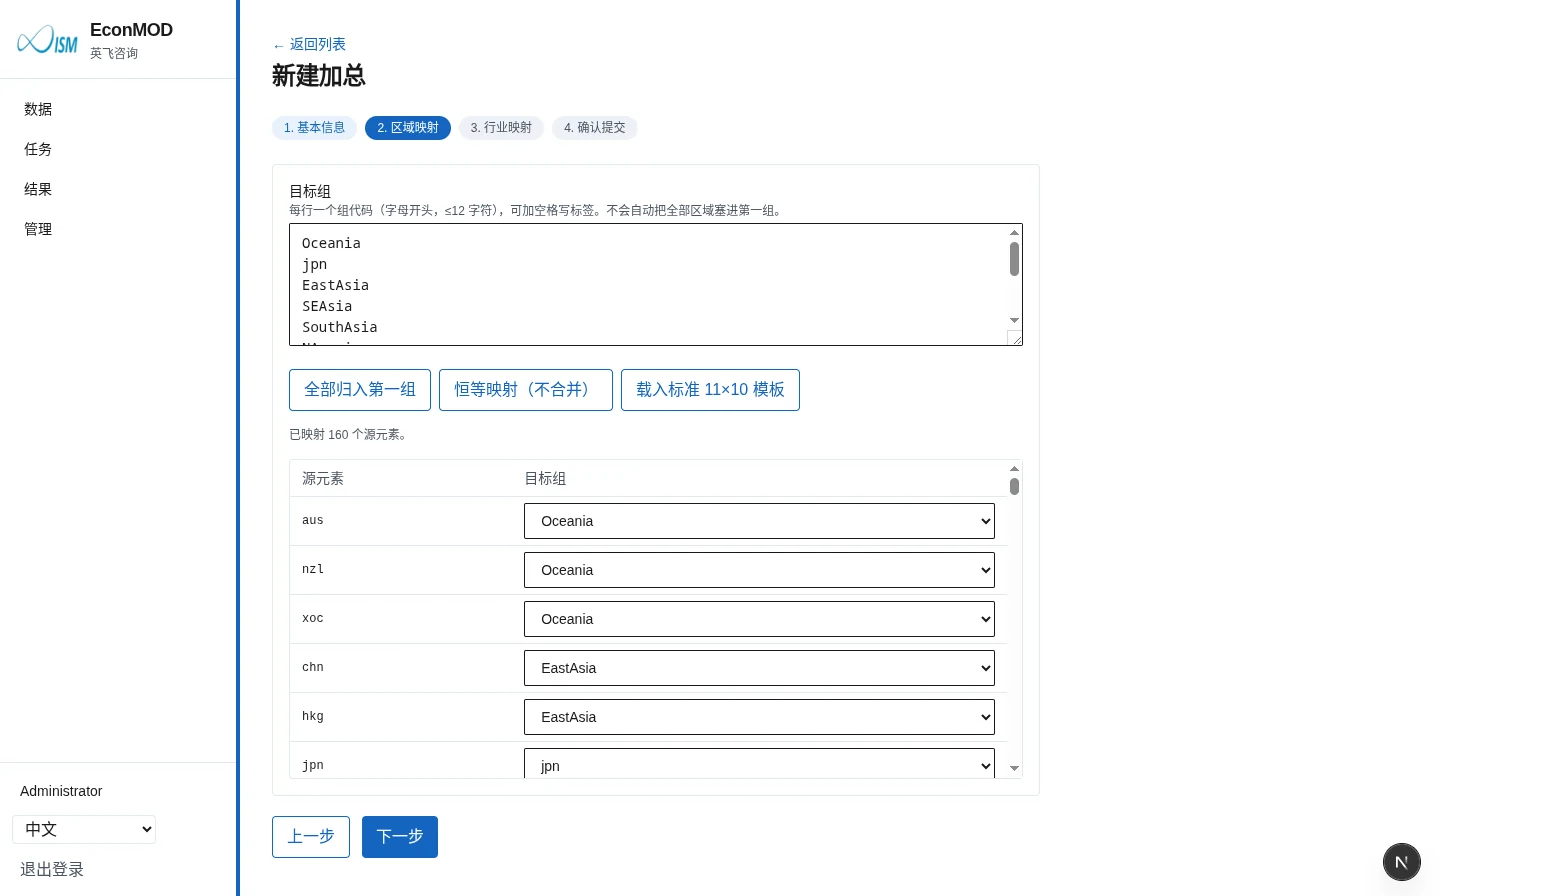
Aggregation: region × sector mapping
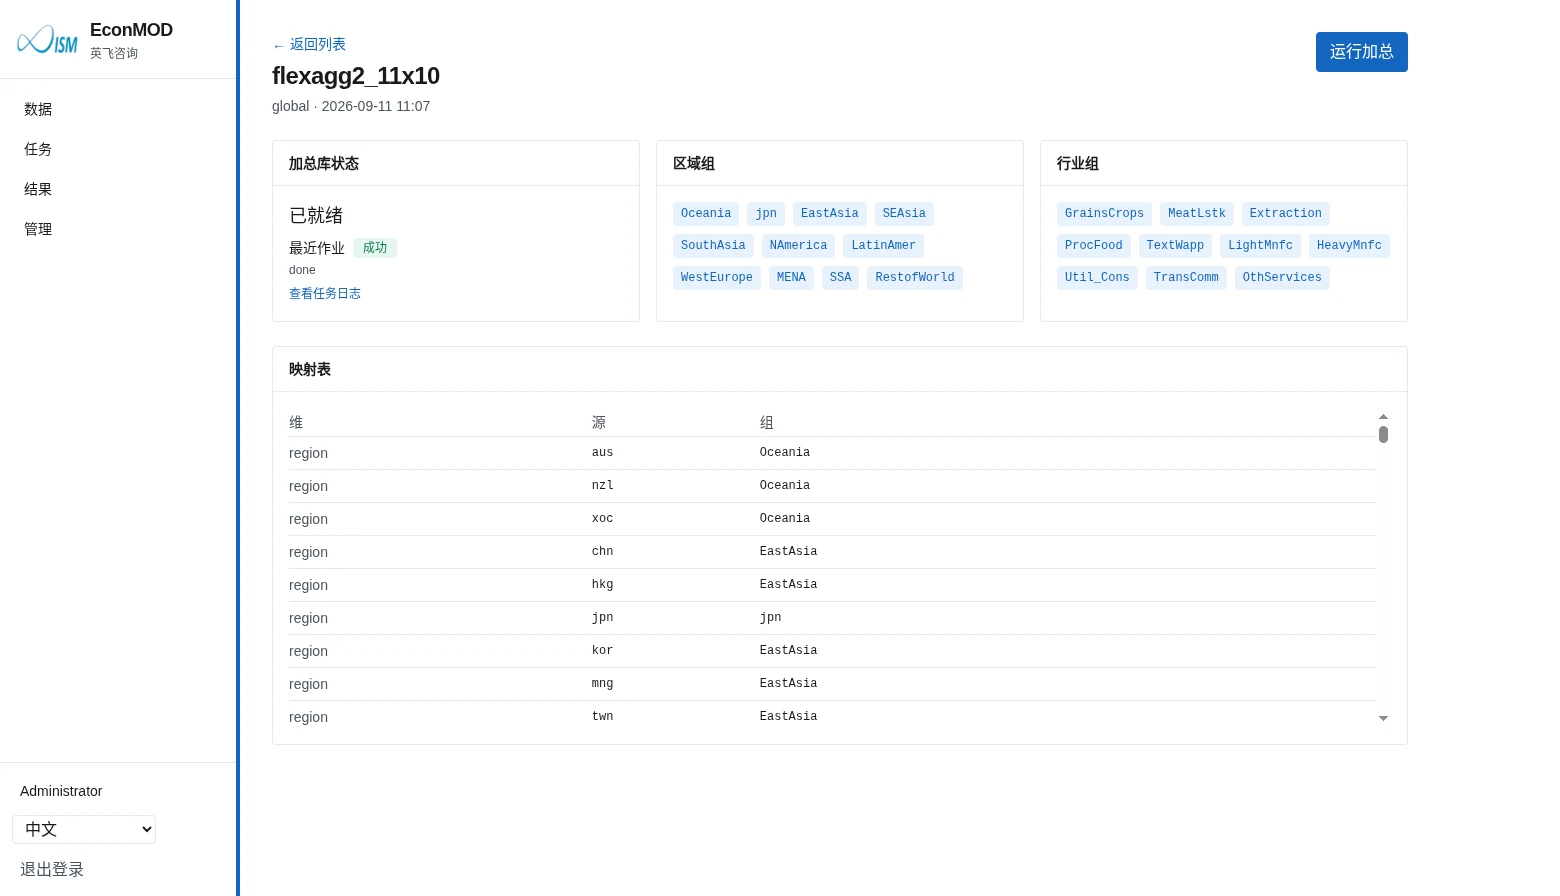
New aggregations use a four-step wizard: basics → region mapping → sector mapping → confirm. Load the standard 11×10 template in one click, or assign target groups element by element.
After a plan is saved, review region / sector groups, the full mapping table, and aggregated-database status, then run the aggregation job.
Closures & shocks: scenario setup
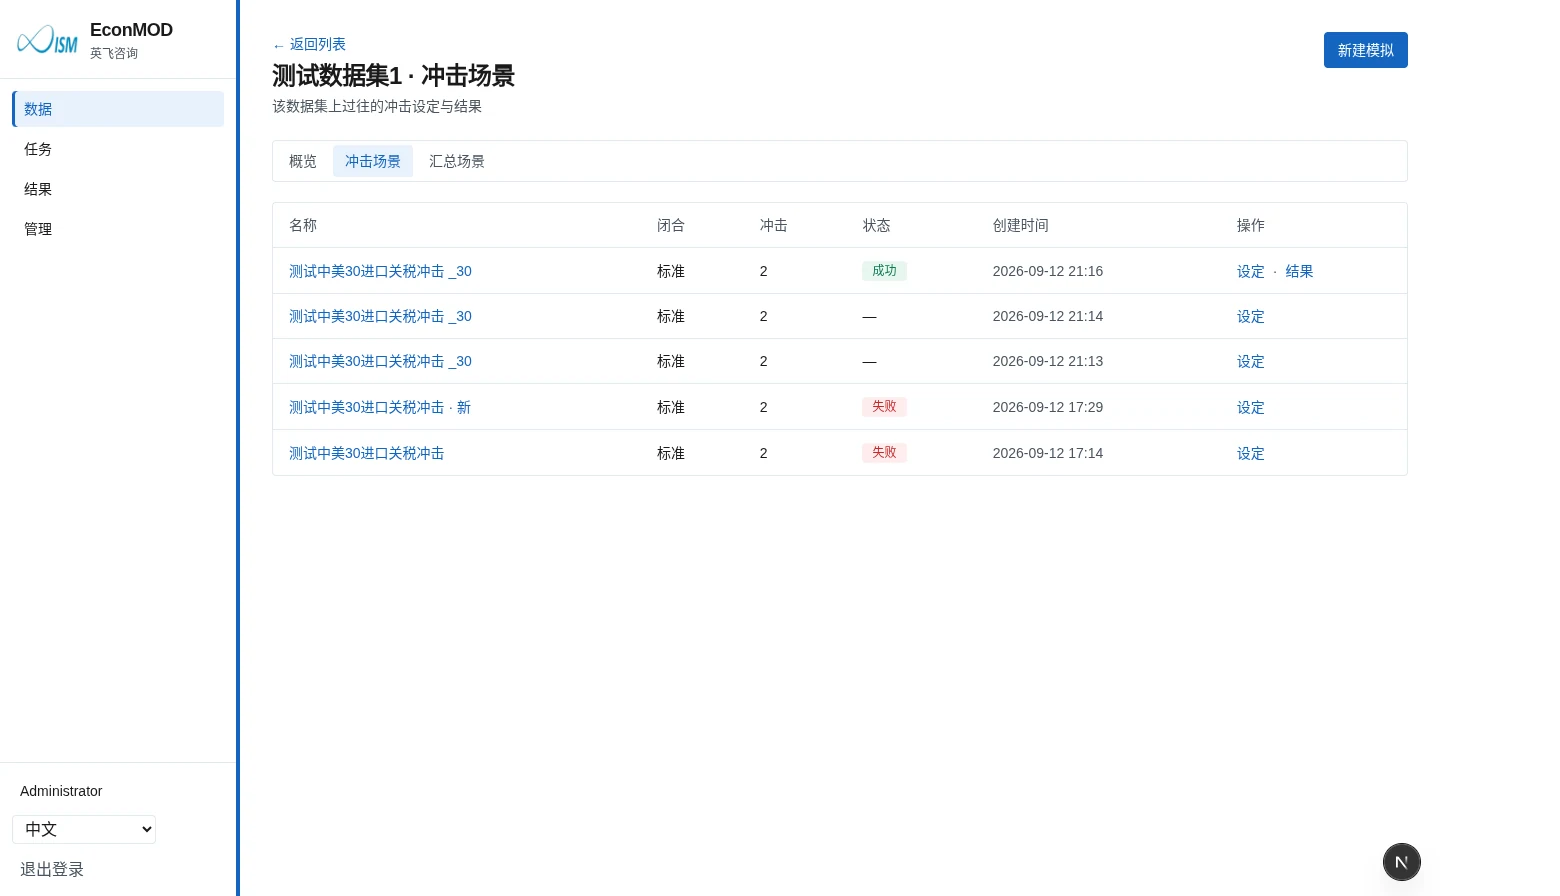
Manage past scenarios on a base’s shock list: closure, shock count, and solve status at a glance, with jumps to setup or results.
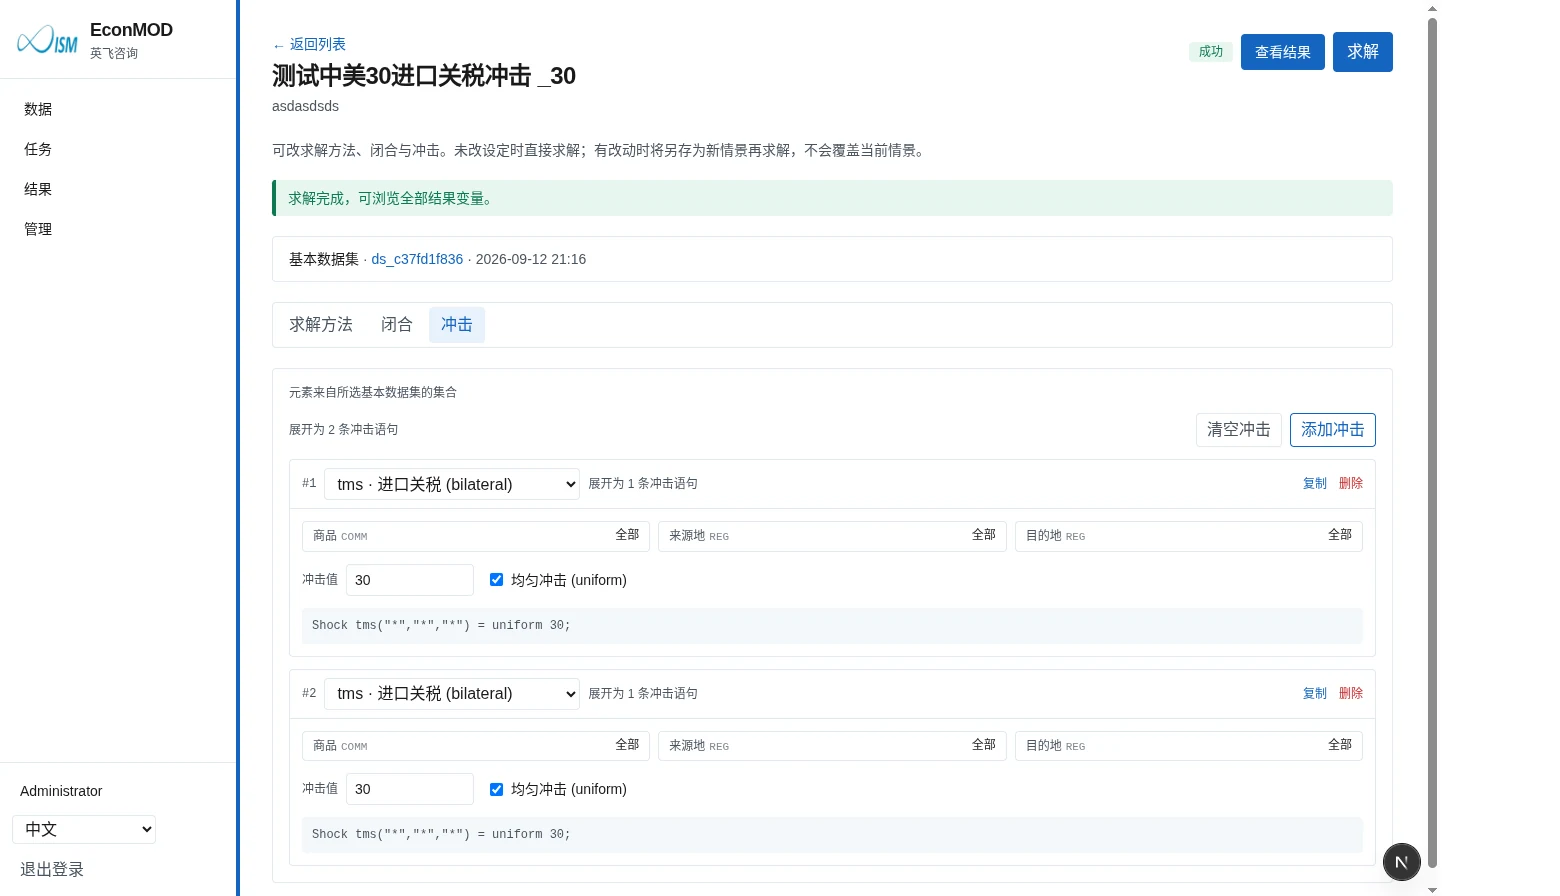
Inside a scenario, switch among Solution method / Closure / Shocks. Shocks support structured edits by set slices (for example bilateral import tariffs tms) and generate checkable shock statements; adjust settings before submit and solve.
Jobs: queue and logs
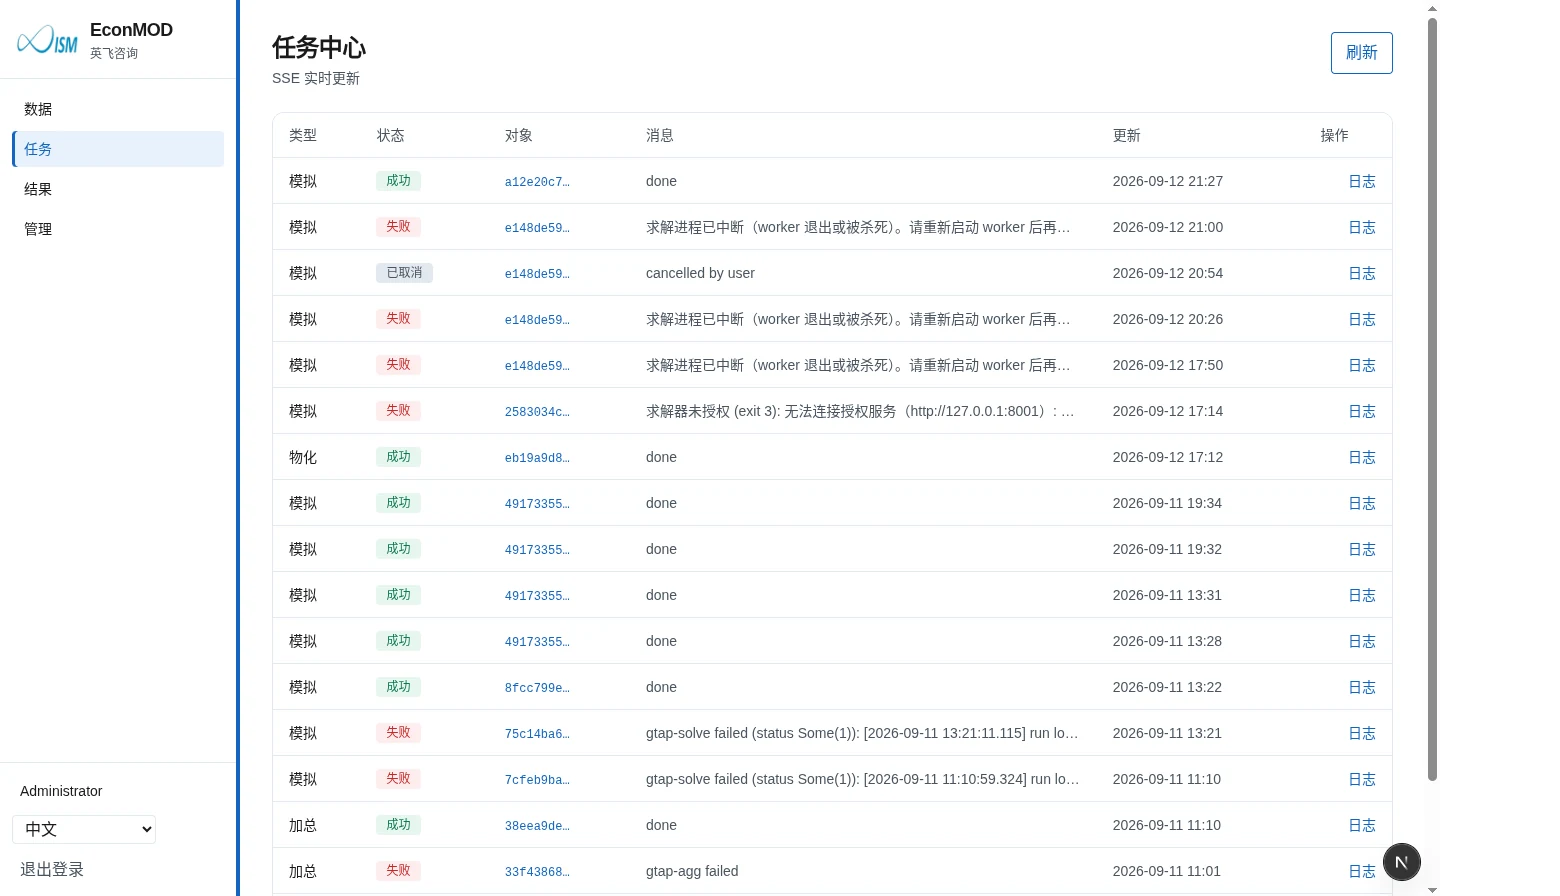
Aggregation, materialization, and simulation jobs queue on the server; the Jobs page refreshes status over SSE and opens logs for diagnosis.
Results: search, browse, and export
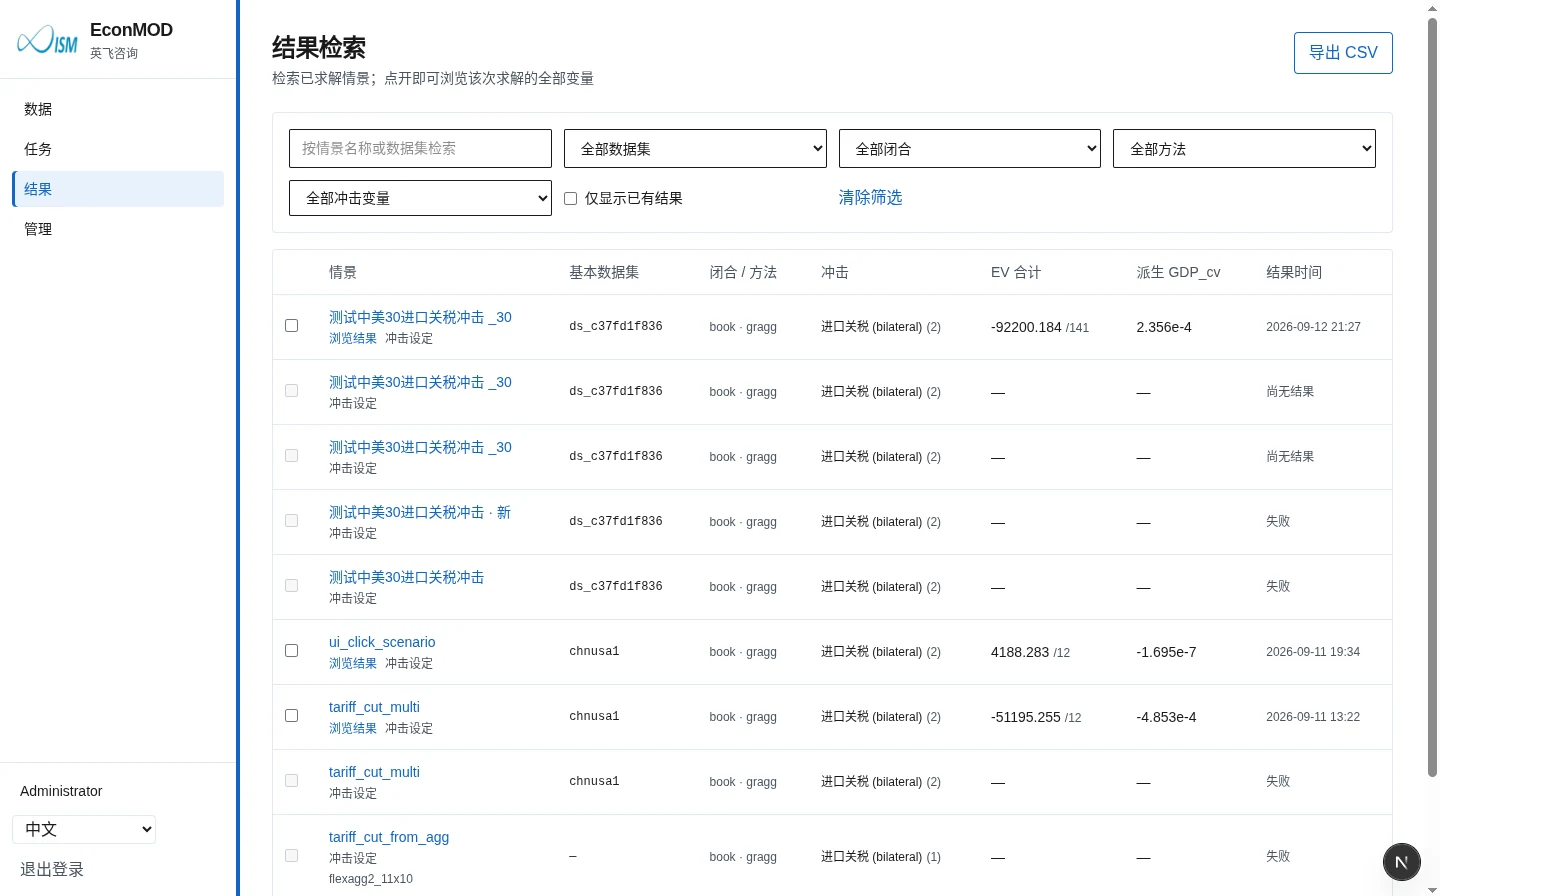
In Results, filter solved scenarios by dataset, closure, method, and shock variables; compare EV / derived macros; export CSV.
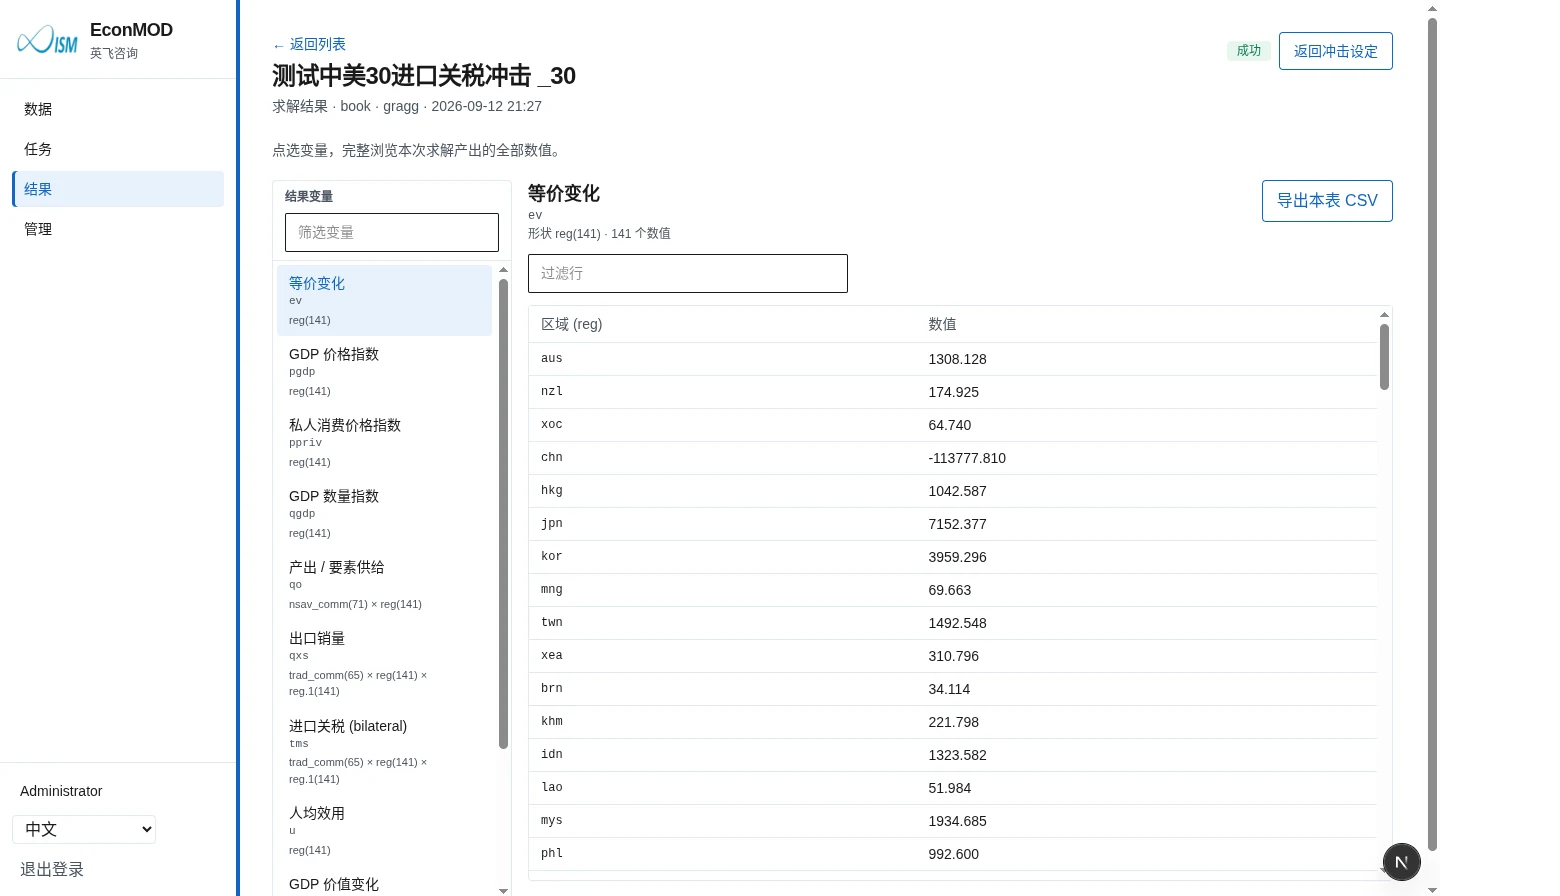
Open a solve to pick result variables on the left and browse full slice values on the right (for example regional welfare ev), with table export.
Deeper capabilities
Aggregation
For GTAP-style base databases, map by region × sector: group codes, labels, order, and mapping completeness are validated before submit.
Full global mappings and standard compressed templates (for example teaching-scale 11×10) save as aggregation plans, run as one-click aggregation jobs, and jump into shock scenarios on the derived database.
Closures & Shocks
Built-in Book / Short / Long / Self closure semantics, plus custom exogenous slices.
Shocks support uniform shocks and structured edits by set slice, or text import; a closure–shock pre-check runs before solve, reducing “failed after half an hour because the variable was not shockable.”
On the same aggregated database you can create scenarios repeatedly—change closure, shocks, or solution steps without remapping dimensions each time.
Solve methods
Path methods familiar to economists are available directly:
- Gragg / Euler / Midpoint, with step groups and Richardson extrapolation;
- Johansen one-step linear;
- Subinterval iteration (iter) for large shocks.
Outputs center on structured results (welfare EV / world EV, derived macros, trade and prices, and more), browsable by variable on the results page for team search and comparison.
Jobs & Governance
Aggregation and simulation jobs queue on the server; the UI tracks status and logs in the job center.
Administrators maintain base datasets, default authorization, and bilingual variable dictionaries—so the team shares one “solvable source of truth.”
Who it is for
- Applied CGE / GTAP analysts: fast iteration on tariffs, productivity, trade policy, and related scenarios;
- Consulting and research teams: shared server compute and base authorization, with auditable project outputs;
- Data and model administrators: publish bases, control access, and maintain variable definitions.
If you are still stitching folders, editing scripts, and hand-aligning closures and shocks on a laptop, EconMOD’s value is immediate: it turns a repeatable modeling process into product features.
Walkthrough: from sign-in to results
Four steps take you through a full path.
1. Sign in to the workbench
Open http://econmod.infsum.com/ and sign in with an assigned account.
2. Choose a database and open a scenario
In Data, pick an authorized base → open an Aggregation scenario (mapping) or a Shock scenario (closure / shocks / solve).
Aggregation path: load a standard template or custom mapping → confirm → run aggregation.
Shock path: create or open a scenario → edit shocks and closure → solve.
3. Track jobs in the job center
After submit, open Jobs for queue and status; on failure, open logs to diagnose.
4. Search and export in Results
In Results, find scenarios, open them to browse all variables, and export CSV as needed.
Need an account or base-database access? Contact Infinite-Sum Modeling.